KEY TAKEAWAYS: SHIFT-RIGHT TESTING
- Shift-left is necessary, but it doesn't catch everything. Real users, real data volumes, and real infrastructure at 2 a.m. behave differently than your staging environment.
- Production is your richest source of quality signal. Stop treating it as where testing ends.
- Incidents become regression tests. Regression tests become guardrails. Close the loop and the same failure never escapes twice.
- Observability-driven testing requires three foundations: instrumentation, blameless culture, and runbooks. Without them, you just create noise.
- Start small: one critical journey, one SLO, one synthetic monitor, one controlled canary. Build incrementally over 6 months.
- Synthetic monitoring validates that real user journeys work from the user's perspective. Canary deployments catch problems before they hit 100% of traffic. Chaos testing exposes hidden assumptions.
- SLOs turn "the application feels slow" into measurable quality expectations that drive release decisions.
- Blast radius, auto-rollback, and kill switches make production experiments safe, not reckless.
- QE, SRE, and development aligned on shift-right means better evidence about how the system actually behaves; not more conflict.
- AI-Led Test Automation accelerates the feedback loop, turning incident analysis into regression tests in minutes instead of hours.
Introduction
For years, the advice in quality engineering has pointed in one direction: shift left. Test earlier. Get QE into design reviews. Catch the defect while it's cheap. It's good advice and it worked - the teams I've been on genuinely found more problems sooner once we took it seriously.
But there's a gap that shifting left never closes, and pretending otherwise has cost us a few uncomfortable Saturdays. No amount of pre-production testing fully predicts how real users, real data volumes, and real infrastructure behave together at 2 a.m. under load you didn't simulate. Staging is a model of production, and models leave things out.
Here's what I've noticed: the teams that get serious about observability-driven testing don't just find problems faster. They understand why they're happening. They spend less time guessing about root cause and more time acting on real signal. When they do catch an incident, they triage it in minutes instead of hours. And the biggest difference? They close the loop - incidents become regression tests, tests become guardrails, and the same class of failure never escapes twice. AI-Led Test Automation accelerates this loop, turning incident analysis into automated regression tests in minutes instead of hours.
Most teams talk about shift-right testing. Fewer actually build it. Which means if you start now, you're ahead of the curve.
Observability-driven testing - the practice of treating production as your richest source of quality signal - isn't about making QE and SRE nervous. It's about giving both teams better evidence about how the system behaves when it matters most. This article covers what that looks like in practical terms and how to bring it in without creating anxiety.
Context & Impact
Monitoring Tells You It's Down. Observability Tells You Why.
Traditional monitoring answers a yes/no question: is the system up? Observability asks the harder question: why is the system behaving this way?
Logs, metrics, and traces give QE another source of evidence without requiring a new build. Observability-driven testing uses that telemetry to understand what real users are doing and where the system behaves differently from expectations.
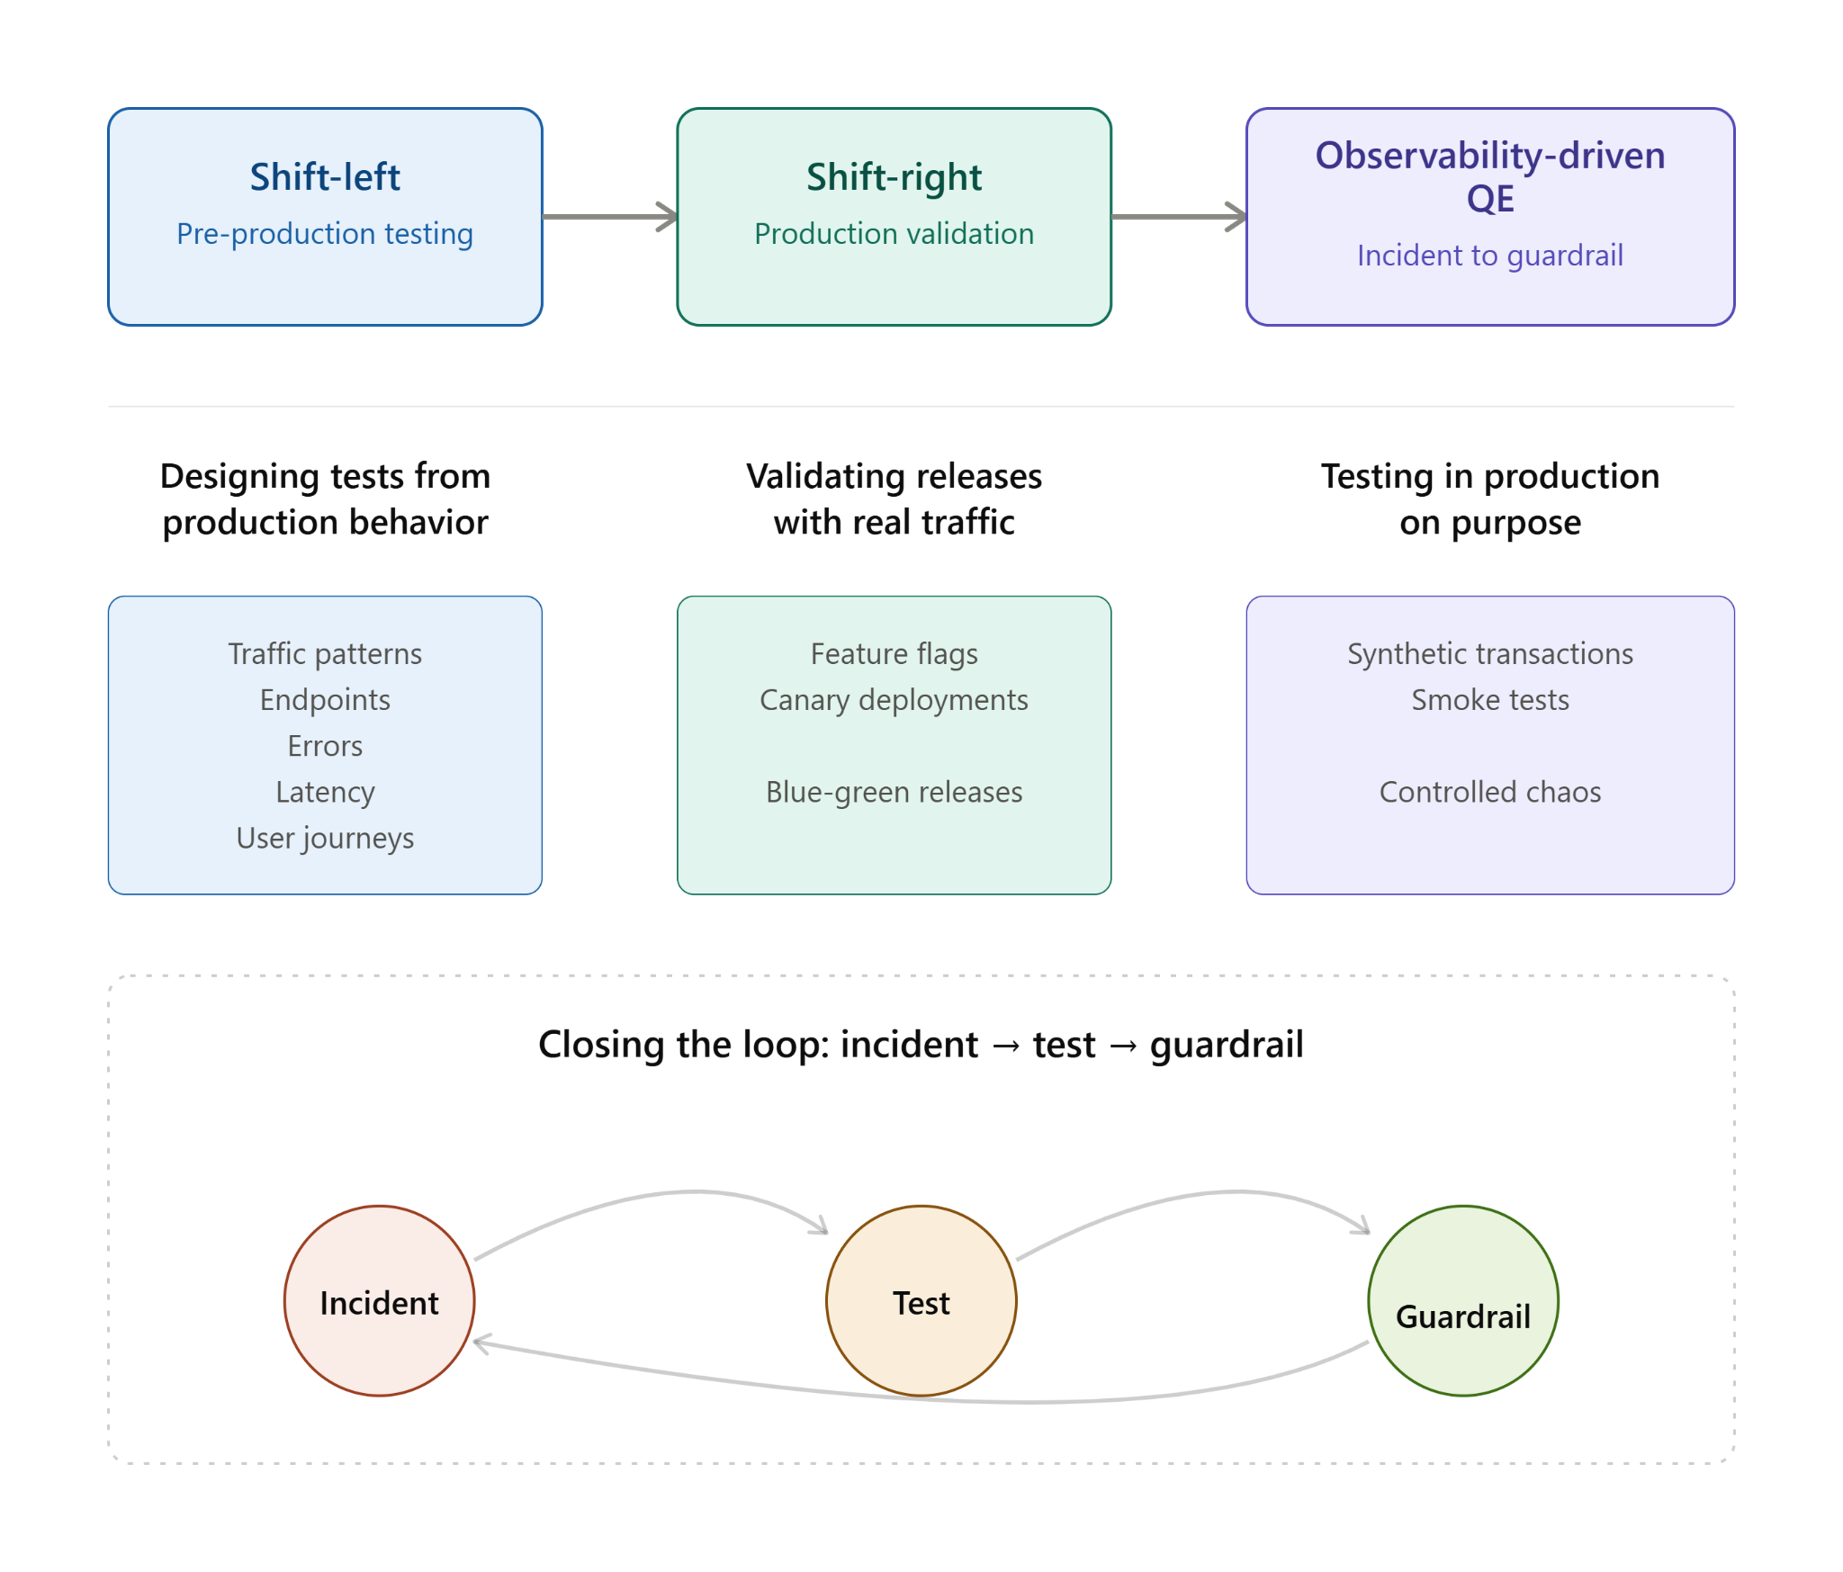
The practical connection looks like this:
Where It Works
The practices worth adopting
Synthetic monitoring
Scripted journeys run in production from multiple regions. The objective isn't to test every feature continuously. It's to make sure the most important user journeys are working from the user's perspective.
Example — Synthetic Playwright Checkout Journey
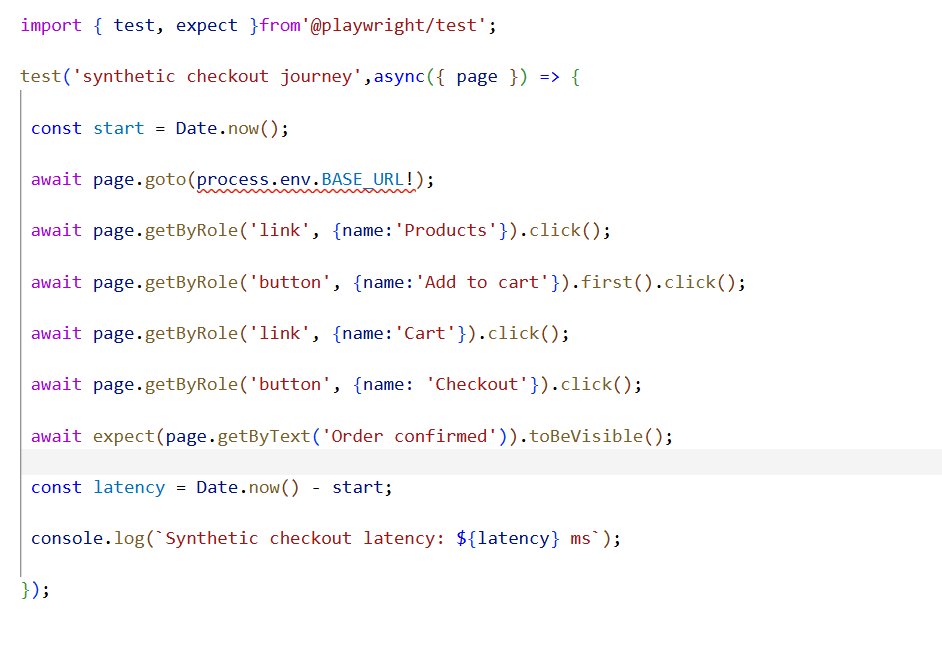
The important distinction is that this should use safe synthetic data and transactions, so the monitor doesn't accidentally create real orders, payments, or customer records.
Canary analysis
A small percentage of real users receives the new release while the system compares the canary against the stable version.
A simple rollout might look like: 5% → 25% → 50% → 100%
At every stage, compare:
- Error rate
- Latency
- Business metrics
- Conversion or completion rate
- Infrastructure health
If the canary crosses the agreed threshold, rollback should happen automatically rather than waiting for someone to notice a dashboard.
Example — Canary Promotion Logic
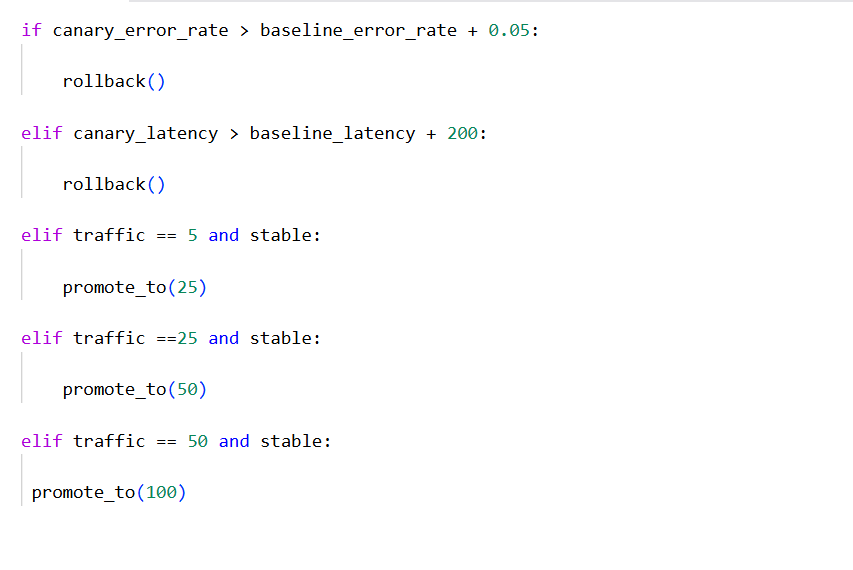
The exact thresholds should be defined for the application rather than copied blindly from another team.
Service level objectives as quality gates
An SLO turns "the application feels slow" into a measurable quality expectation.
For example:
Checkout SLO
- Success: 99.5% of checkout requests succeed during the monthly measurement window.
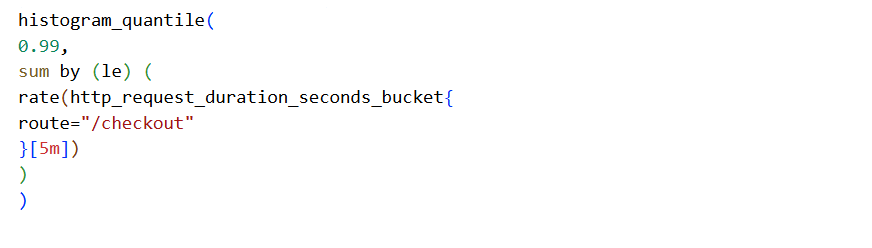
- Latency: 99th-percentile checkout latency remains below 2 seconds. Learn how to validate SLO compliance under production load.
That gives the team an error budget of 0.5% for failed checkout requests. When the error budget is healthy, the team can continue normal delivery.
When the budget is being consumed quickly, quality risk becomes a release decision rather than simply another dashboard notification.
Example — Prometheus p99 Latency Query
Example — Checkout Error Rate
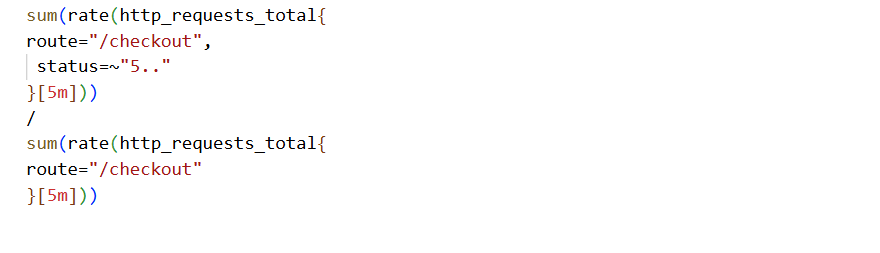
QE shouldn't just consume these numbers. QE should help define which customer journeys matter, what "good" looks like, and which thresholds should influence release decisions.
Chaos and resilience testing
Controlled failures expose assumptions that normal functional testing rarely touches.
The rollout should be deliberate:
Stage 1 — Staging
Test failure scenarios in a controlled environment.
Stage 2 — Production Canary
Introduce the failure against a limited production scope, such as 5%.
Stage 3 — Scheduled Production Experiments
Run approved experiments during a defined window with the right teams available.
Possible scenarios include:
- Database replica unavailable
- API response slowdown
- Dependency timeout
- Memory pressure
- Network degradation
Example — Database Replica Failure Experiment
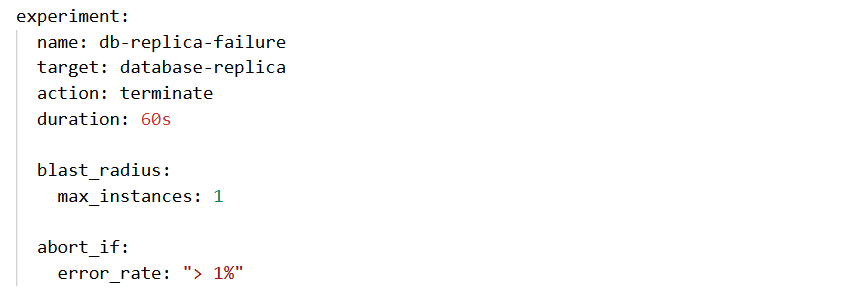
The YAML is an illustrative experiment definition; the actual implementation depends on the chaos platform being used.
Every experiment needs guardrails: automatic rollback, a kill switch, a defined blast radius, and clear abort conditions.
Feeding incidents back into the suite
Every significant incident should answer one question:
What test or guardrail would have caught this earlier?
For example, imagine a payment-processing incident where a transient payment-provider failure caused an incorrect retry behavior. The incident is resolved, but the work shouldn't end there.
The regression test should reproduce:
- First payment attempt fails temporarily.
- Retry occurs.
- Second attempt succeeds.
- Customer sees one successful payment.
- Duplicate payment is not created.
- Monitoring confirms expected behavior.
Example — Incident-to-Test
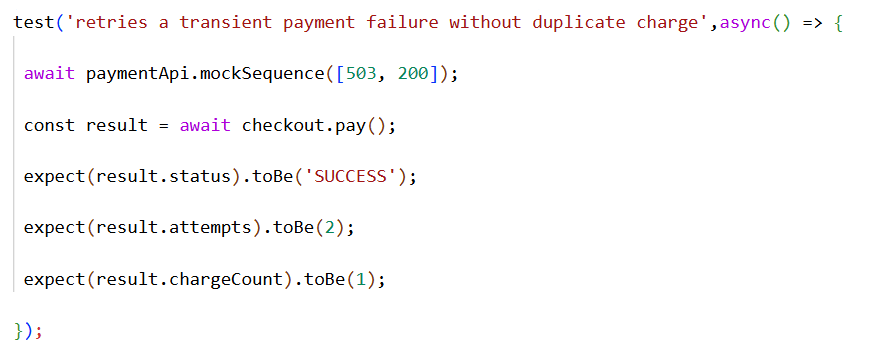
The important part isn't the exact test syntax. It's the feedback loop:
Incident → Root cause → Regression test → Monitoring rule → Future guardrail
Tools & Implementation
Tools ecosystem
There isn't one correct observability stack. The right choice depends on scale, existing infrastructure, engineering maturity, and budget.
Monitoring
Datadog
Good fit when a team wants a managed observability platform with broad integrations and less infrastructure to maintain.
Prometheus + Grafana
A strong option for teams that want flexibility and an open-source foundation and are comfortable operating the stack.
New Relic
Useful for teams looking for an integrated application-performance and observability platform.
Synthetic testing
Playwright DIY
Good when QE wants maximum control over journeys, assertions, test data, and CI/CD integration.
Managed synthetic monitoring
Useful when the organization wants less operational maintenance, distributed execution, and built-in monitoring capabilities.
Canary deployment
Flagger
Useful for Kubernetes-oriented progressive delivery.
Spinnaker
A broader continuous-delivery platform for organizations with more complex deployment requirements.
Cloud-native deployment controls
Often the simplest choice when the cloud platform already provides the required traffic-shifting and rollback capabilities.
The decision should start with the problem to solve, not the tool name.
Want to understand how AI accelerates these decisions? Listen to our podcast on How AI is Reshaping Modern Quality Engineering
Risks & Governance
Blast radius
Start with small traffic percentages, automatic rollback, and a kill switch.
Data integrity
Synthetic transactions should never pollute analytics, fulfillment, financial reporting, or customer data. Test traffic should be clearly tagged and isolated.
Alert fatigue
Tie alerts to SLOs and actual user impact rather than creating alerts for every metric fluctuation.
Privacy
Sensitive telemetry should be scrubbed, tokenized, or excluded before it reaches analysis systems.
Organizational readiness
QE, development, and SRE need to agree on the purpose of production testing. The goal is learning and resilience, not assigning blame.
Prerequisites
Before introducing shift-right testing at scale, I would want three things in place:
- Instrumentation — logs, metrics, traces and useful business telemetry.
- Blameless culture — incidents are treated as learning opportunities.
- Runbooks — teams know what to do when an experiment or release crosses a threshold.
Without these foundations, production testing can create more noise than value.
Implementation Roadmap
How I'd start
Rather than trying to implement everything at once, I'd build the capability month by month.
Month 1 — Visibility
Instrument the most important user journeys and establish baseline metrics.
Month 2 — Synthetic Monitoring
Automate the top three critical production journeys.
Month 3 — SLO
Define at least one meaningful SLO and start tracking error-budget consumption.
Month 4 — Canary
Canary a single service and automate the comparison between stable and canary versions.
Month 5 — Chaos in Staging
Introduce controlled failure scenarios in staging and validate the rollback process.
Month 6 — Production Chaos
Run a carefully controlled 5% production experiment.
Month 7+
Normalize the feedback loop:
Incident → Test → Alert → Guardrail → Better release
Measuring Success
Six-month target metrics
The exact baseline will differ by organization, but a useful target framework could look like this:
Metric | Starting Point | Six-Month Target |
MTTD | 15 min | 2 min |
MTTR | 45 min | 12 min |
Production incidents | 8–12/month | 3–4/month |
Escaped defects | 5–8/month | 1–2/month |
On-call pages | 12–15 | 3–5/week |
The numbers matter less than establishing a baseline and proving that the practices are moving it in the right direction.
Conclusion & Next Steps
Shift-left is necessary. But modern systems are distributed, data-hungry, and used in ways no test plan can completely anticipate.
Observability-driven testing stretches QE across the entire lifecycle. Production telemetry helps decide what to test. Real traffic validates what pre-production environments cannot fully reproduce. Incidents become regression tests, and those tests become guardrails for future releases.
The goal isn't to test less before release.
It's to stop treating release as the end of testing.
For a mature quality engineering organization, shift-right is not about putting QE in conflict with SRE or development. It's about giving all three teams better evidence about how the system behaves when it matters most.
The next step is to start small: one critical journey, one SLO, one synthetic monitor, and one controlled canary.
Then measure the result.
Production shouldn't be treated as a place where testing stops. With the right observability, guardrails, and culture, it can become one of the richest sources of quality intelligence the team has.
Ready to build shift-right practices at scale?
Explore TO THE NEW's Quality Engineering Services for end-to-end support: observability strategy, synthetic monitoring setup, SLO definition, canary deployment automation, and ongoing governance.